DeepSeek Joins Hands with Unitree: When Intelligence Becomes Cheap Enough to Waste
Text by Sleepy @sleepy0x13
Technology truly begins to change the world when it becomes cheap enough to be wasted.
Recently, even foreign media have started learning a term from the Chinese internet: "kill line."
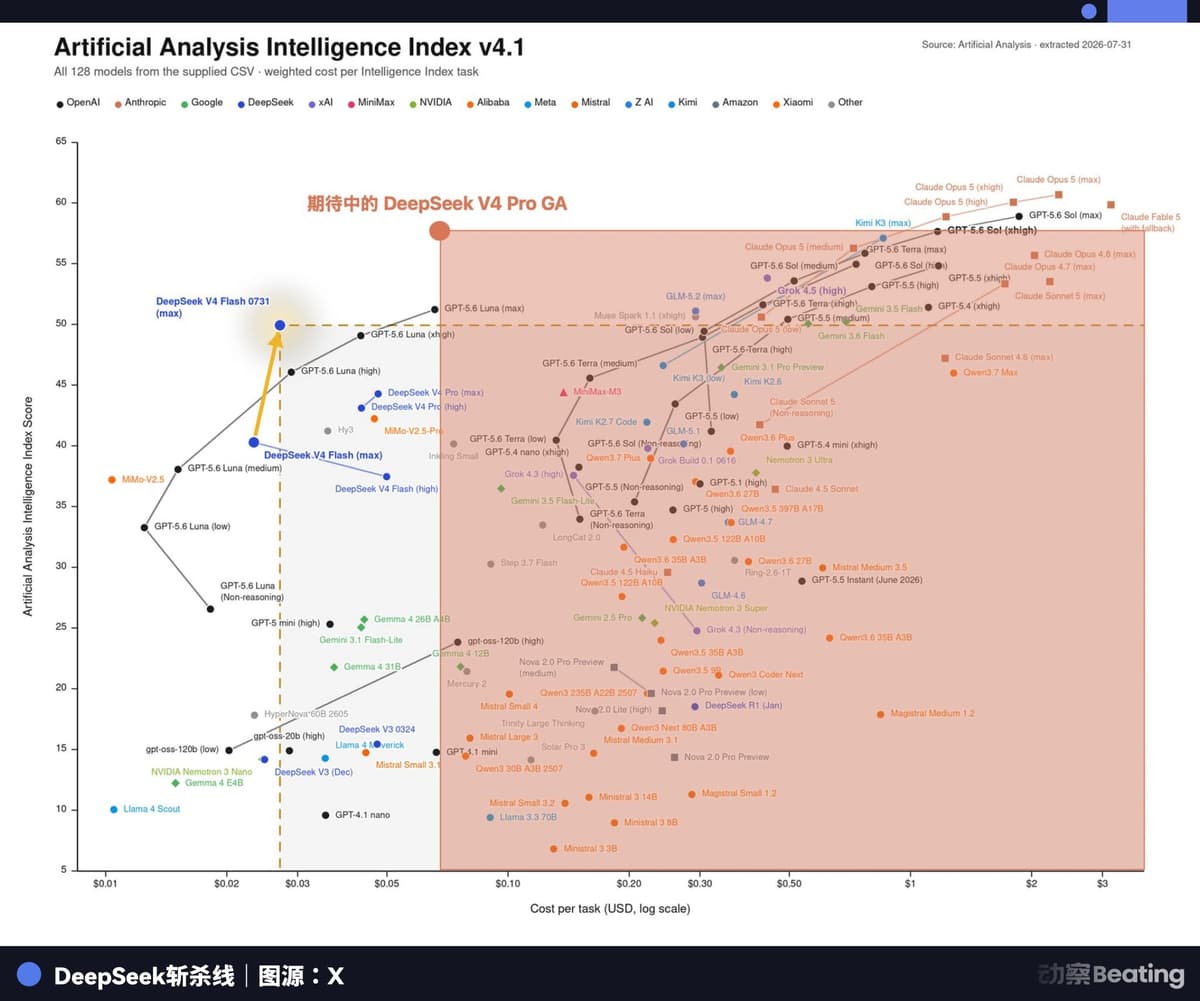
On July 31, DeepSeek V4 Flash was updated. On the Artificial Analysis coordinate chart comparing model intelligence and usage cost, the vertical axis goes up for smarter models, and the horizontal axis goes right for higher costs. The V4 Flash's intelligence index reached 50 points, already close to the global top tier, yet the average cost per test round was only 3 cents. That point was almost pushed to the upper-left corner of the coordinate system. Models cheaper than it are mostly less capable; models smarter than it are generally much more expensive.
Now, if a model isn't significantly better than DeepSeek, it becomes increasingly difficult to justify why it should be dozens of times more expensive. The Chinese internet calls this boundary the "kill line." A few days later, Bloomberg discussed the price pressure Chinese models exert on U.S. AI companies, directly using "Death Zone" in the headline.
Starting from the V2 model in 2024, DeepSeek has been continuously driving down the cost of "thinking once" for machines. The tasks models can accomplish are becoming more complex, but the price hasn't followed the rising capability. Over the past two years, the large model industry has been accustomed to boasting progress with larger parameters, longer contexts, and higher benchmarks. DeepSeek has been chasing another standard: for the same intelligence, can we spend less money?
On the other side of Hangzhou, Wang Xingxing has been doing something similar for over a decade.
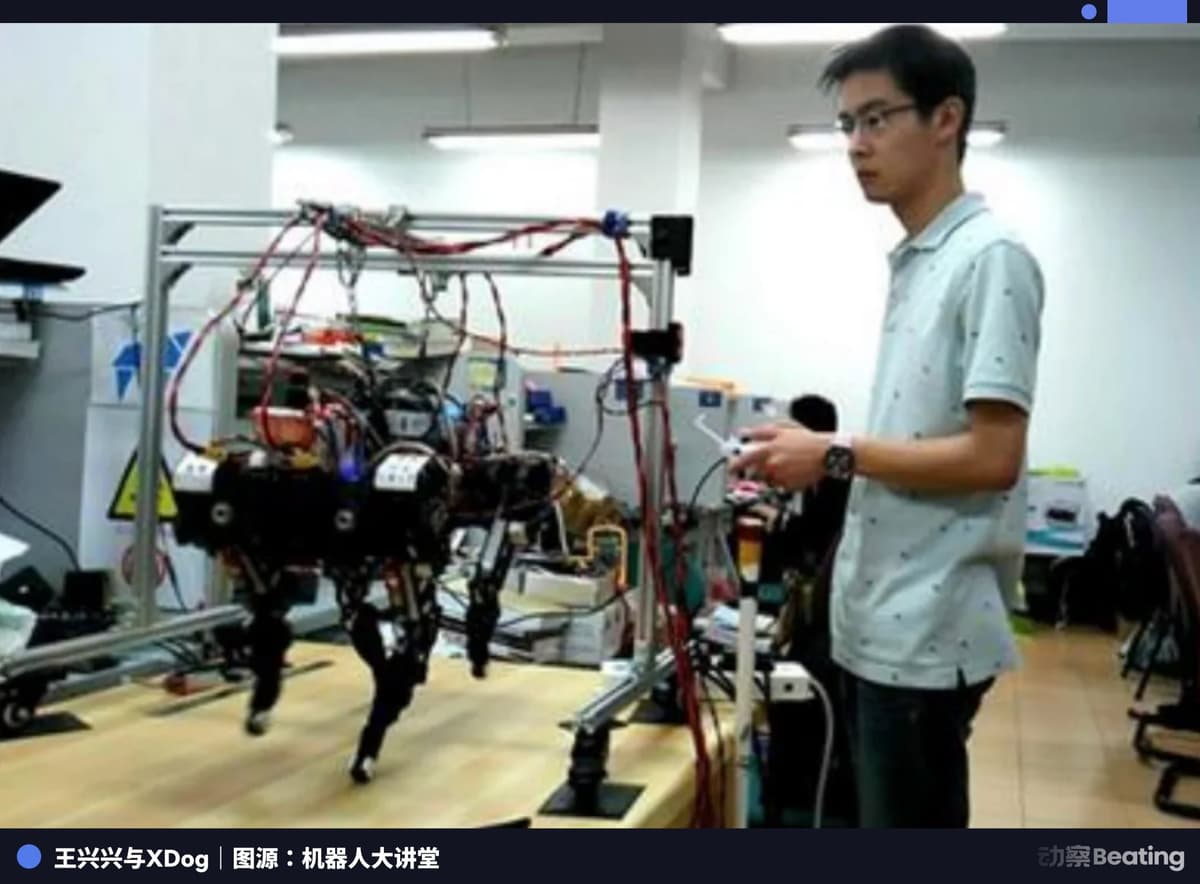
When he was a graduate student working on XDog, he didn't have much money to burn. Expensive hydraulic systems were out of reach, so he studied low-cost motors; mature solutions were unaffordable, so he designed his own driver boards, wrote programs, and built control systems. Many of the technical choices that have now become standard components of Unitree's products were originally driven by a simple engineering habit: don't ask what the industry usually does; first see if there is a cheaper way.
Wang Xingxing later recalled that when he was building a bipedal robot in 2010, the mechanical parts cost only 200 yuan in total. Years later, when someone asked if Unitree could continue to reduce costs, he replied: "Don't try to beat us on cost reduction; we can keep lowering it a lot."
One company is lowering the price of thinking, and the other is lowering the price of action. For a long time, though they were both in Hangzhou, they were still walking their own paths.
Until August 6.
Unitree Technology announced the strategic placement results for its STAR Market IPO. DeepSeek invested 140.8 million yuan to subscribe to Unitree's new shares. The cooperation arrangement disclosed by both parties is also quite straightforward: when Unitree needs model training services and technical solutions, it will prioritize DeepSeek; when DeepSeek needs robots and wants to explore embodied AI applications, it will prioritize Unitree.
This amount of money is not astonishing in today's AI industry. What is truly interesting is that two people who have been trying to turn expensive technologies into cheap commodities for over a decade have finally connected their cost curves. This raises a more compelling question than "the large model finally gives the robot a body":
If the cost of machine thinking and the cost of machine action both continue to decline, what will AI eventually become?
The answer may not just be "more people can afford it."
The bigger change is that we will no longer have to cherish it so much.
Two Price Slashers
The most similar thing between Liang Wenfeng and Wang Xingxing is that they both don't believe in cheapness achieved through subsidies. Price lists can be changed overnight, but there's no free lunch; this kind of low price usually doesn't last long. If you want to sell something cheap in the long run, you have to go back to engineering and dismantle the costs that were originally taken for granted, layer by layer.
DeepSeek-V2 is the most typical example. After the model was released in 2024, the domestic large model industry was quickly dragged into a price war. The most visible thing to the outside world was the API pricing, but what truly supported the price cuts was hidden in the model architecture. V2 had a total of 236 billion parameters, but only 21 billion were activated when processing each token. Compared to the previous generation, training costs were reduced by 42.5%, KV Cache by 93.3%, and maximum generation throughput increased by 5.76 times.
By V3, this approach continued to advance. The model became larger, using 2.788 million H800 GPU hours for formal training. DeepSeek further optimized efficiency through mixture of experts, low-precision training, and communication optimization.
This cost philosophy later even began to define the product.
In May this year, DeepSeek turned the original 75% promotional discount on V4-Pro into a permanent price, and also continued to lower the flagship tier. Liang Wenfeng previously explained their pricing principle: price based on real costs, don't subsidize in the long term, and don't pursue excessive profits.
Wang Xingxing's understanding of robotics is almost identical.
In an interview with "LatePost" in 2025, he was asked whether the H1 initially sold for $90,000, and later the more flexible G1's low-end version started at only 99,000 yuan. Was that still profitable?
Wang replied: "Business behavior must have reasonable commercial profits. Cost has always been our KPI for everything we do; the core is to make money."
He then talked very little about the common phrase "as scale increases, suppliers will naturally lower prices." What truly determines the lower limit of robot prices is how the motor is chosen, how the reducer is made, how many parts a joint uses, whether the whole machine can be lighter, and which components must be kept in-house.
This way of reducing costs has a strong industrial-era texture: squeezing every penny.
Shortening a circuit board by a few centimeters, removing two parts from a joint, changing the routing of a wire harness—none of these alone is a great breakthrough, but when dozens of such changes are stacked together, they ultimately affect the selling price.
Unitree's price changes over the past few years are exactly like this. In 2023, the first-generation full-size humanoid robot H1 was launched, selling only 5 units that year at an average price of 593,400 yuan. In 2024, the smaller G1 entered the market, with sales increasing to 410 units and an average price dropping to 260,700 yuan. By the first nine months of 2025, humanoid robot sales reached 3,551 units, with an average price falling further to 167,600 yuan.
Every time the price drops a notch, the robot's buyers also change. A device costing 500,000 to 600,000 yuan requires laboratory project approval, budget writing, and justification of what research it will be used for; 100,000 to 200,000 yuan can already enter more universities, development teams, and enterprises.
Many technologies truly cross the threshold of普及 (popularization) through such changes. From a special budget to a departmental budget, then to a regular purchase, and finally one day, people can't be bothered to calculate the cost for each use.
Expensive technologies are naturally only used to solve expensive problems. When prices drop, those trivial matters that were not worth the technology's attention in the past begin to enter its world.
Two Cost Curves Finally Intersect
Unitree is already working on world models and VLA (Vision-Language-Action), so DeepSeek's value is not just about "giving the robot a brain." What truly can lock the two companies together is the most expensive training loop in embodied AI today.
Half of this loop happens in the real world. The robot actually reaches, walks, and grabs things. Humans or other systems continuously demonstrate to it, generating trajectories of success and failure.
The other half happens in computation. Data is cleaned, labeled, and fed into the model to train new strategies, then through inference and verification, redeployed back to the robot. The robot goes out and tries again, brings back new data, and the model learns again. The faster this loop runs, the more of the world the robot encounters.
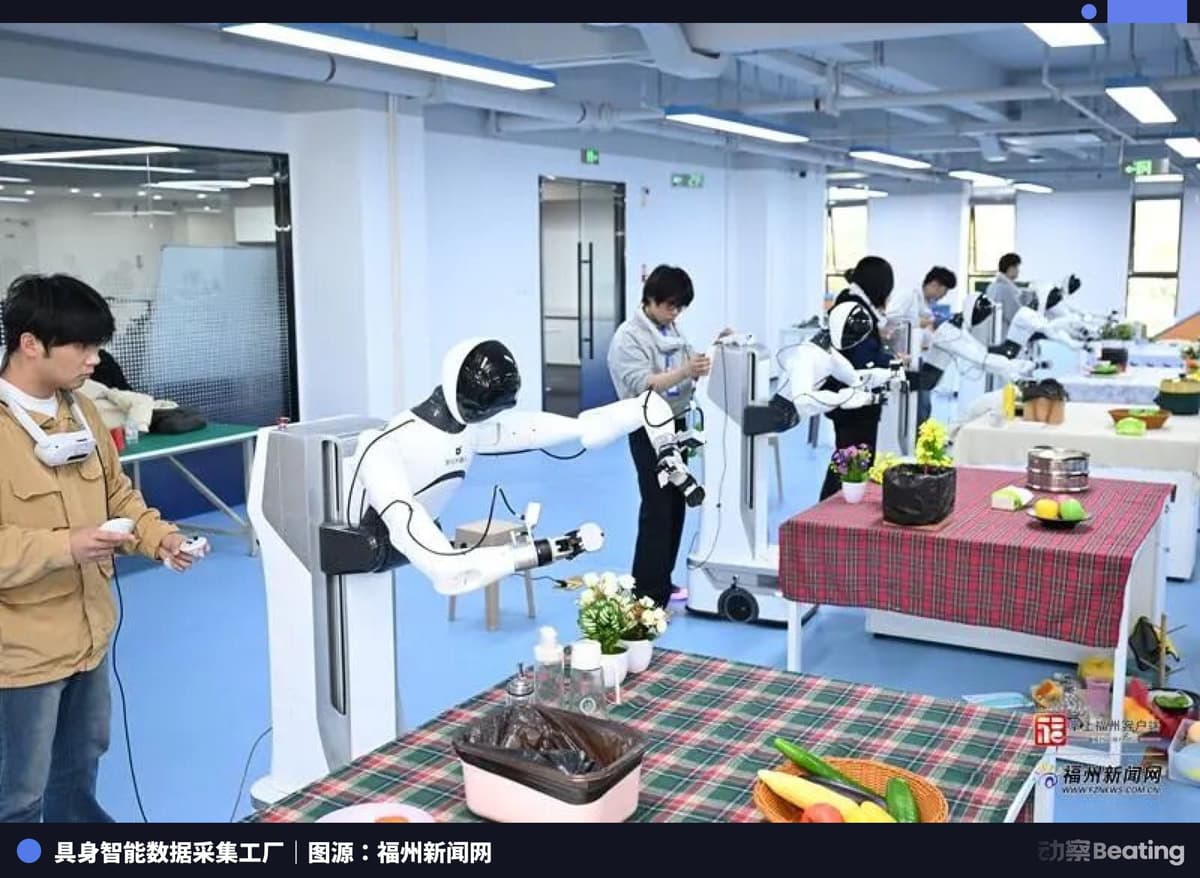
The problem is that both ends are expensive. If the real robot is expensive, the team can hardly let hundreds of robots fall over in the lab all day; if training and inference are expensive, those data that don't show immediate value are hard to train and verify repeatedly.
So in the past, doing robot experiments was always precious. There were only a few robots, and you had to think carefully about what data to collect today. With limited computing power, you had to calculate whether a batch of trajectories was worth running again. The more expensive the resources, the more researchers tended to pick problems that seemed most valuable and had the highest probability of success.
But the real world is not like that.
What's the difference between a cup placed three centimeters from the edge of the table versus five? Where should you grab a towel when it's half wet? When a drawer gets stuck, should you keep pulling or first push back a little? How should the arm adjust when a plastic bag contains one apple versus three apples? None of these things alone is worth a press conference, or even a dedicated lab project. But once a robot enters homes, restaurants, warehouses, and offices, the world it faces every day is precisely composed of these trivial, annoying problems.
Now, looking at the cooperation between DeepSeek and Unitree, the logic becomes much clearer.
Unitree pushes down the cost of the first half, allowing more real robots to enter labs, development teams, and real scenarios. DeepSeek has long been solving the second half, making model training, inference, and verification cheaper and cheaper.
Most trajectories will never end up in a product, most experiments won't produce news, and some robots may fail to grab a cup a hundred times in a row. A batch of expensive data might only prove that the initial idea was fundamentally wrong.
When resources are expensive, these are called "wasting money"; when costs are low enough, they can be called "experience."
If a phone is cheaper, more people can buy it. If a robot is cheaper, it also means it can afford to have more unproductive time, practicing in the lab for an afternoon, doing movements that will never be used, entering more strange environments, and encountering more situations the engineers hadn't thought of in advance.
When both the body and intelligence become cheaper, the first thing embodied AI gets is more room to make mistakes.
How Humans Learned to Waste Technology
This kind of thing has happened many times in human technological history.
In 1865, British economist William Stanley Jevons studied steam engines and coal and discovered a counterintuitive phenomenon. As steam engines became more efficient and burned less coal per task, the total coal consumption in Britain did not decrease; instead, it increased. Because once steam power became cheaper, people started using it for things they previously wouldn't dare to. The coal saved by efficiency was quickly consumed by new demands.
This later became known as the "Jevons paradox."
Over the past two years, people using AI have already experienced the opposite phase to some extent. When models were still expensive, we first learned how to save intelligence. Startup teams talked about user experience, but product managers still had to remember a Token price list. A feature might be technically feasible, but could be cut because "running the model five more times per user is too expensive."
But for technology to truly enter life, it often has to cross another threshold: it becomes cheap enough that we start using it for things that aren't that important.
Today, no one calculates the economic value of turning on a living room light for an hour, and no one feels they are wasting the great internet infrastructure because their phone sends a few extra network requests in the background.
Electricity and networks both have costs, but those costs are already low enough that it's not worth making a decision for each use. People have long become extravagant in these matters, without any guilt.
If intelligence one day reaches this point, our relationship with AI will also change. After a meeting, you casually ask the model to summarize it. After writing an article, you have several models critique it separately. If an Agent fails, you try a few different paths. There's a saying: "Shoot first, ask questions later." A robot cleans the table, knocks over a cup the first time, reaches wrong the second time, moves too slowly the third time—then it tries a fourth time.
Once a technology is truly popularized, people will not calculate its usage efficiency more seriously; they will even forget they are using it.
When We Stop Counting This Ledger
In 1911, British mathematician and philosopher Alfred North Whitehead wrote in "An Introduction to Mathematics":
"Civilization advances by extending the number of important operations which we can perform without thinking about them."
Today's AI has clearly not reached this point yet. We are still discussing which tasks are worth using the most expensive models; developers still switch suppliers because of a few yuan difference per million tokens; robot companies still have to find the easiest scenario to account for between exhibition halls, labs, and factories. This industry still has a heavy sense of daily necessities.
And this 140.8 million yuan investment truly links together a bill that has rarely appeared in industry discussions: How much does it cost for a machine to make one mistake?
Today, the answer is still not cheap enough, so every piece of real-world data must be carefully collected, every round of training must be selective, and every robot should find a job that can produce output as soon as possible.
On the day intelligence truly becomes ubiquitous, there may not be a press conference announcing the arrival of a new era. We will just slowly notice that a robot has been practicing picking up boxes in a corner of the warehouse for an afternoon, failing three hundred times, and no one bothers to ask; an Agent tries dozens of paths to find an answer, and no one watches the token bill with worry; placing a few more robots in the lab no longer requires writing a purchase justification for each one.
So the truly important price of AI in the future may not be how much one million tokens cost, nor how much a humanoid robot costs, but when we finally can't be bothered to calculate these numbers.
When machines can think a few more times, take a few more steps, make a few more mistakes, without anyone feeling sorry, then intelligence will have truly transformed from an expensive capability into infrastructure.
Technology truly begins to change the world when it becomes cheap enough to be wasted.
DeepSeek is bringing thinking close to this price, and Unitree is bringing the body close to this price. The rest is to give machines a life that is cheap enough.
Cheap enough to try repeatedly, cheap enough to make mistakes continuously, cheap enough that those failures that seem meaningless today eventually become numerous enough to form intelligence.
-END-